
How we work
Four steps, in order. Each one has to earn the next — we do not ask you to commit to a build before you have seen the method work on your own data.
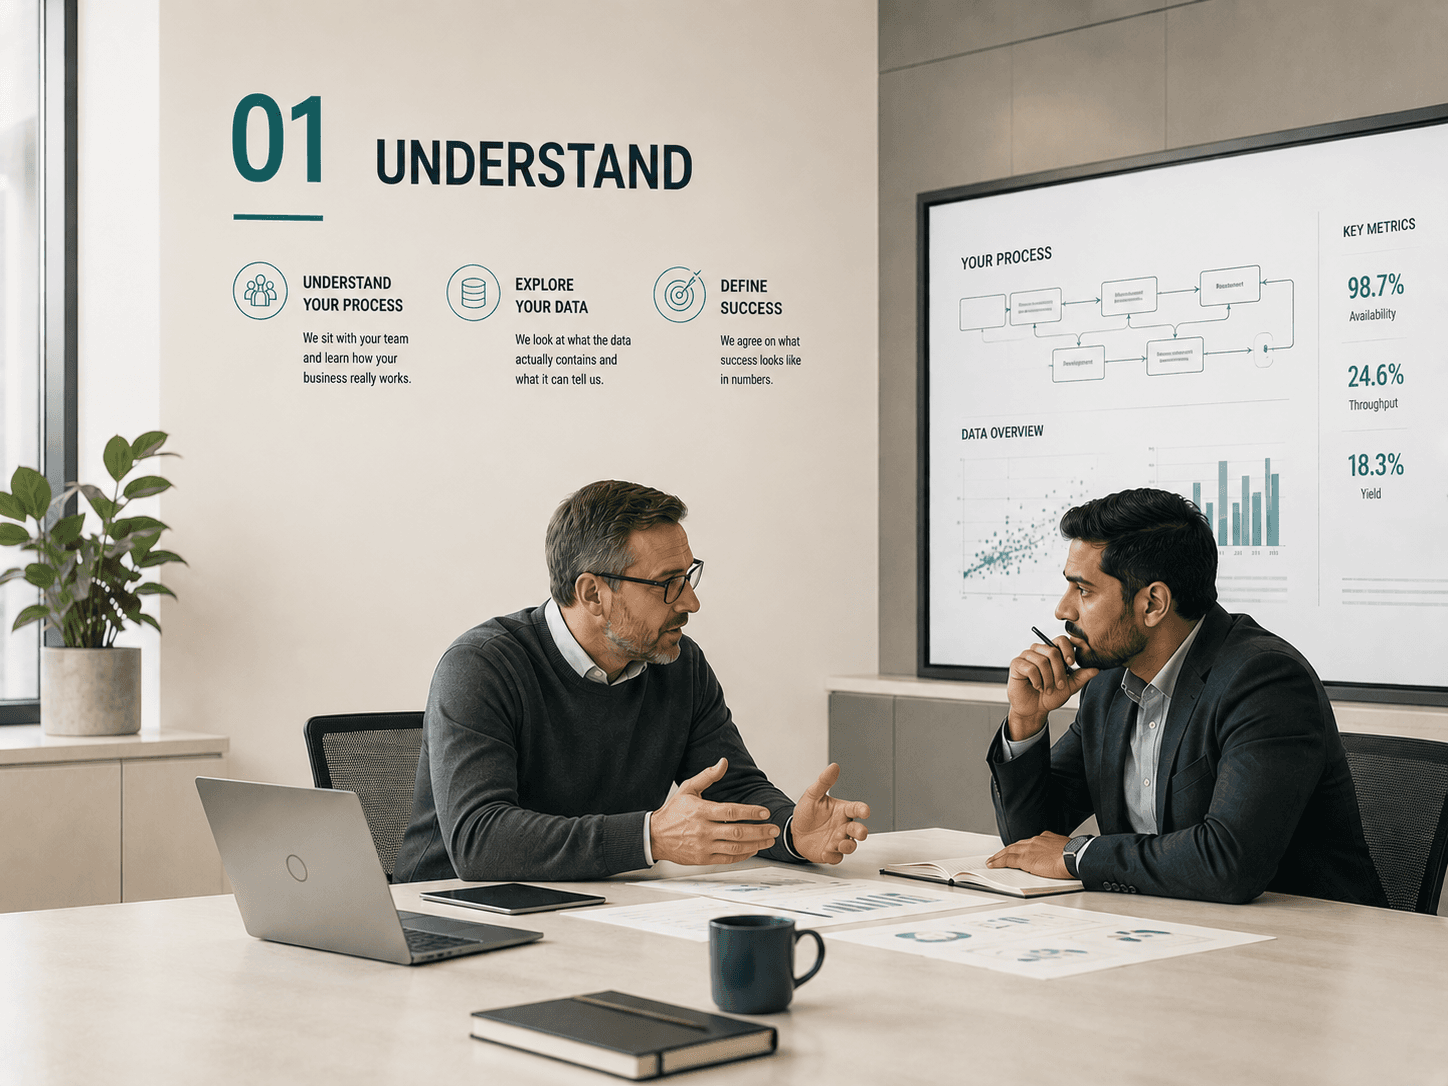
Understand
We sit with your process and data before proposing anything.
Most failed AI projects were aimed at the wrong problem. We start on site or with your team, look at what the data actually contains, and agree on what success would look like in numbers. If we think AI is not the right answer, we will tell you at this stage rather than sell you a project.
- Site visit and process walkthrough
- Data review and feasibility assessment
- Agreed success metrics before any build
Prove
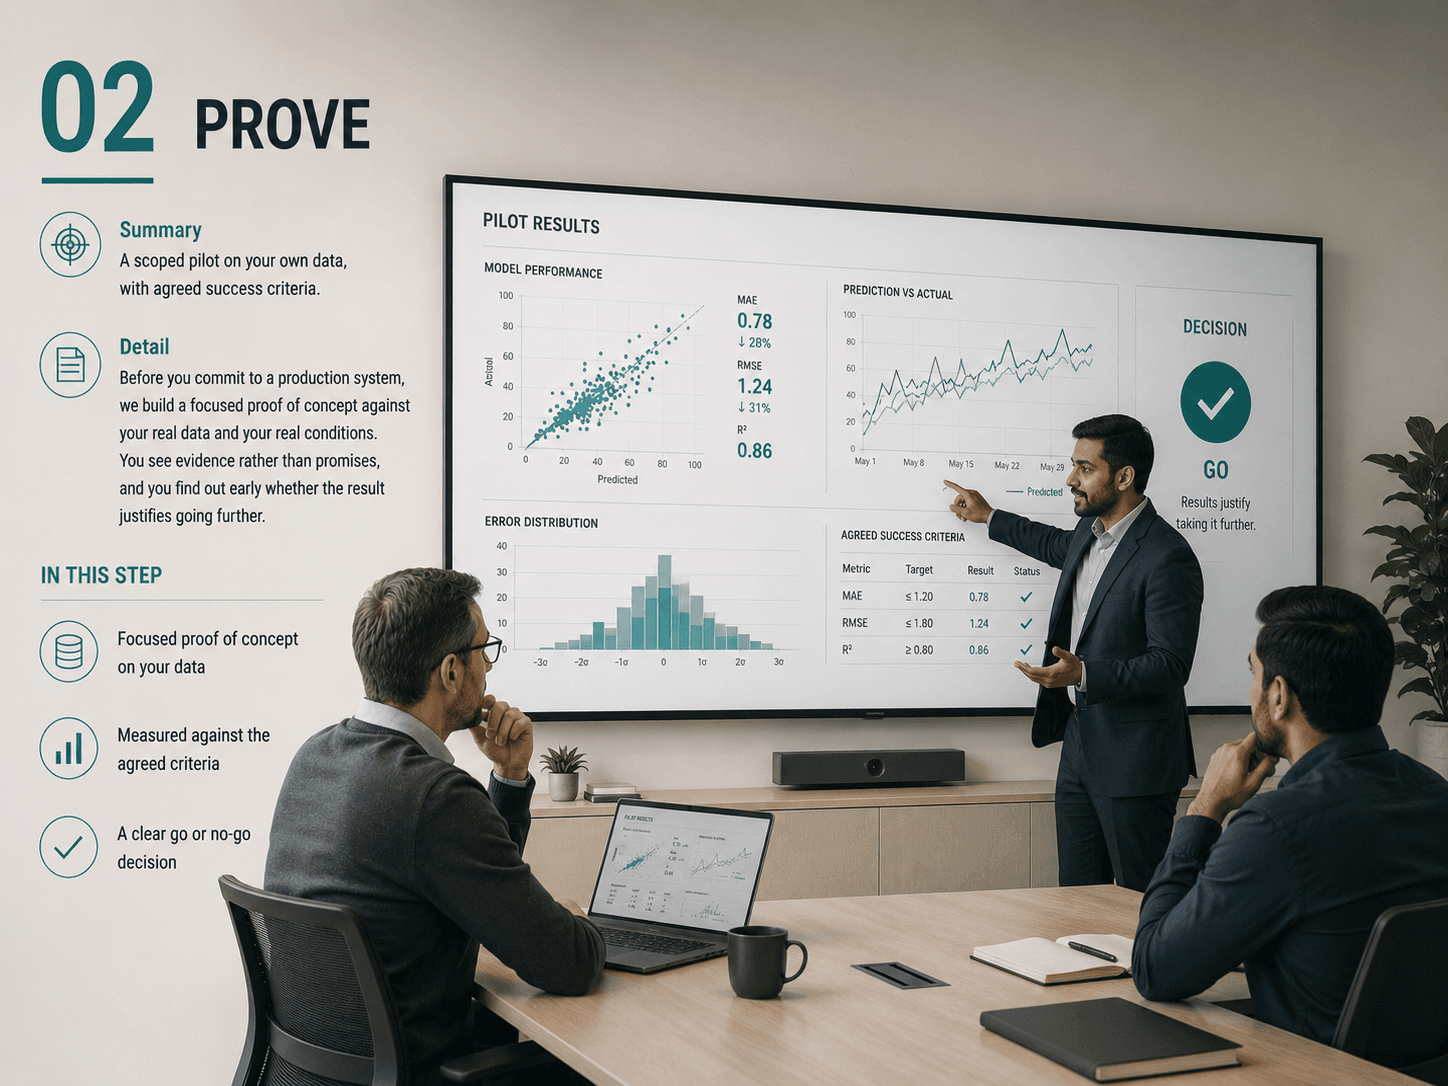
A scoped pilot on your own data, with agreed success criteria.
Before you commit to a production system, we build a focused proof of concept against your real data and your real conditions. You see evidence rather than promises, and you find out early whether the result justifies going further.
- Focused proof of concept on your data
- Measured against the agreed criteria
- A clear go or no-go decision
Build
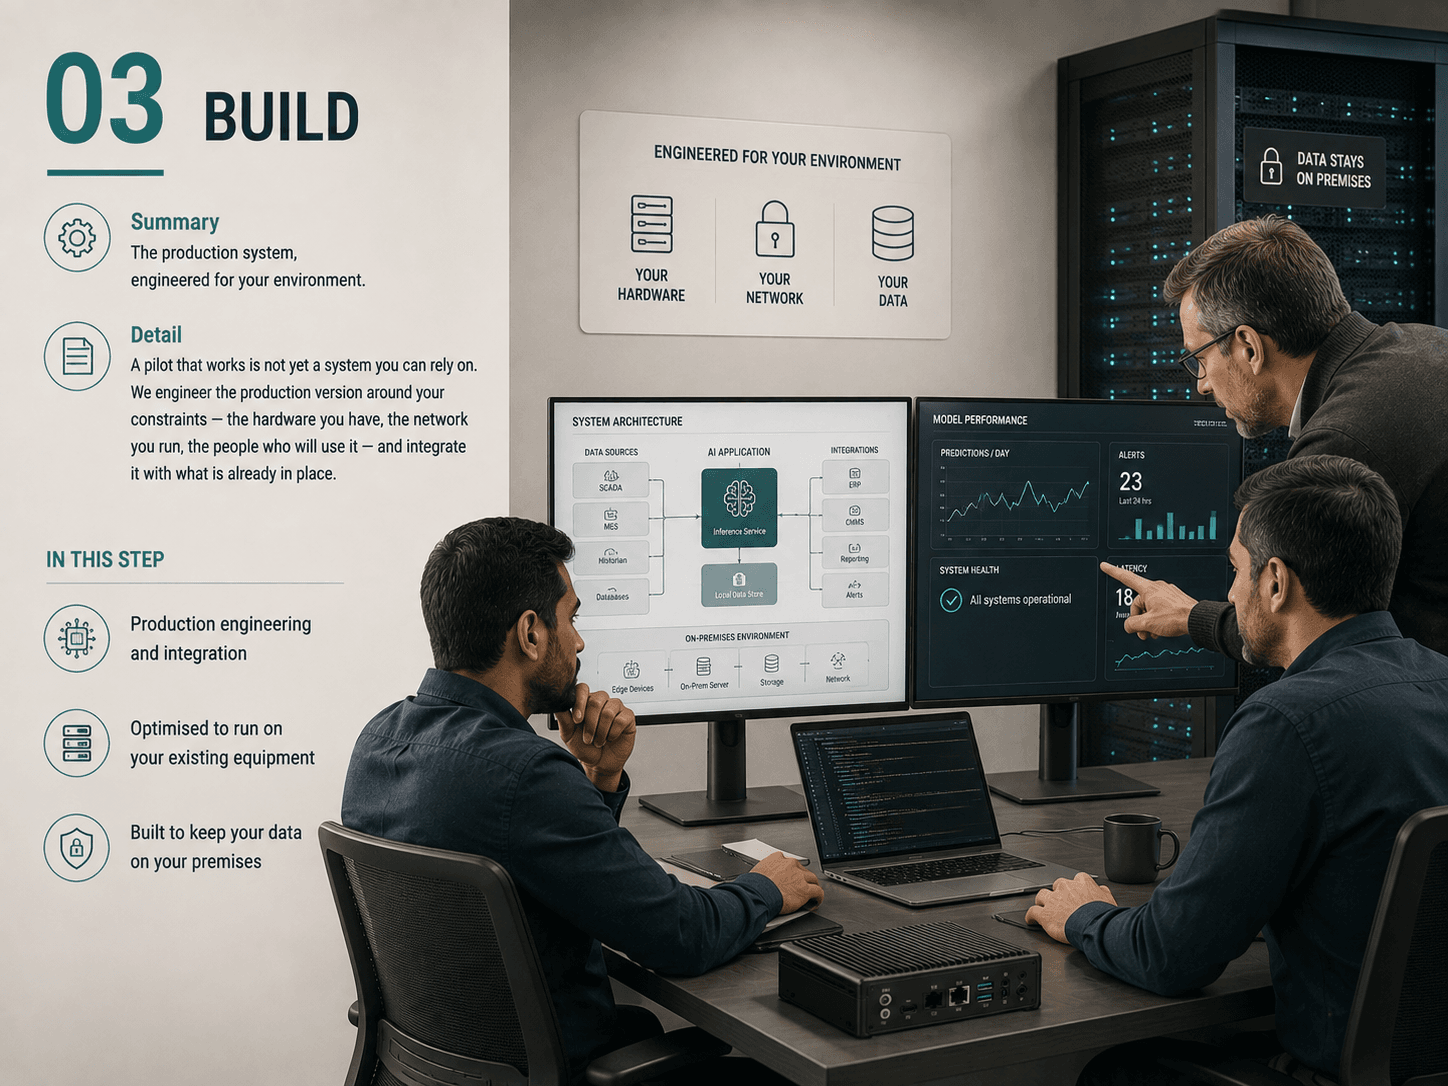
The production system, engineered for your environment.
A pilot that works is not yet a system you can rely on. We engineer the production version around your constraints — the hardware you have, the network you run, the people who will use it — and integrate it with what is already in place.
- Production engineering and integration
- Optimised to run on your existing equipment
- Built to keep your data on your premises
Deploy
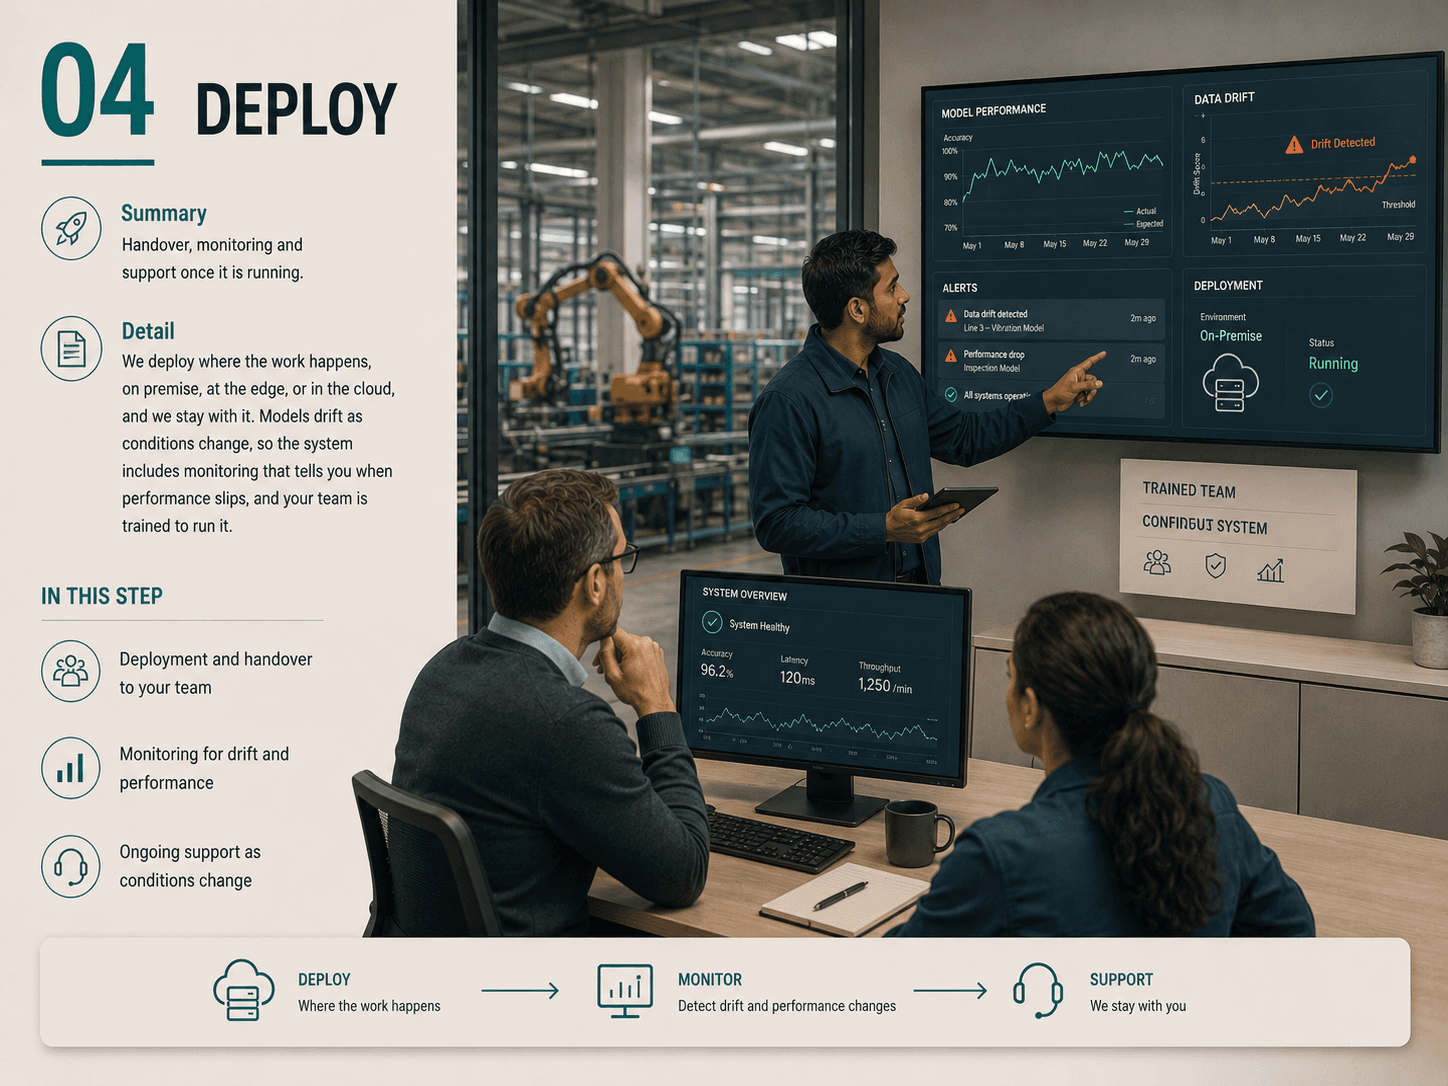
Handover, monitoring and support once it is running.
We deploy where the work happens, on premise, at the edge, or in the cloud, and we stay with it. Models drift as conditions change, so the system includes monitoring that tells you when performance slips, and your team is trained to run it.
- Deployment and handover to your team
- Monitoring for drift and performance
- Ongoing support as conditions change
Low risk, no lock-in, honest answers
Low risk
You decide whether to continue after the pilot, not before it.
No lock-in
The system runs on your infrastructure, with your data.
Honest answers
If AI is the wrong tool for your problem, we say so early.